I am currently a Master student at the Department of Computer Science and Technology, University of Science and Technology of China (USTC), supervised by Prof. Zhenya Huang at the State Key Laboratory of Cognitive Intelligence.
My research interest includes large language models and agentic coding.
📝 Publications
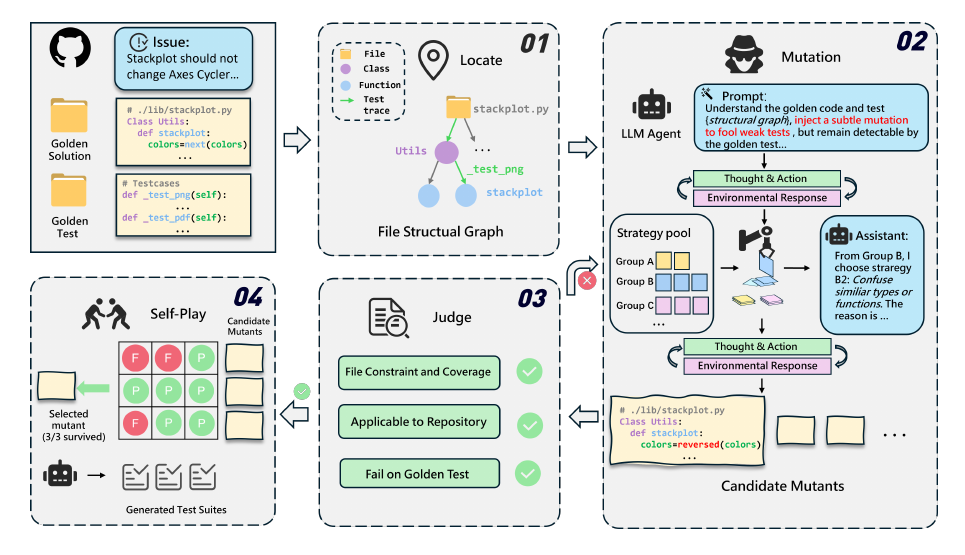
SWE-Mutation: Can LLMs Generate Reliable Test Suites in Software Engineering?
Yuxuan Sun, Yuze Zhao, Yufeng Wang, Yao Du, Zhiyuan Ma, Jinbo Wang, Mengdi Zhang, Kai Zhang, Zhenya Huang
Findings of the Association for Computational Linguistics: ACL 2026, 39651–39674
PDF · Code & Data · arXiv
- Introduces a benchmark that stress-tests LLM-generated test suites with realistic semantic mutants. Its agentic pipeline locates mutation scopes, generates and judges candidate bugs, and uses self-play to retain hard mutants; the final benchmark contains 2,636 mutants from 800 instances, including a nine-language subset. Even DeepSeek-V3.1 reaches only 10.20% verified reproduction and 36.15% relative detection, exposing a substantial test-generation gap.
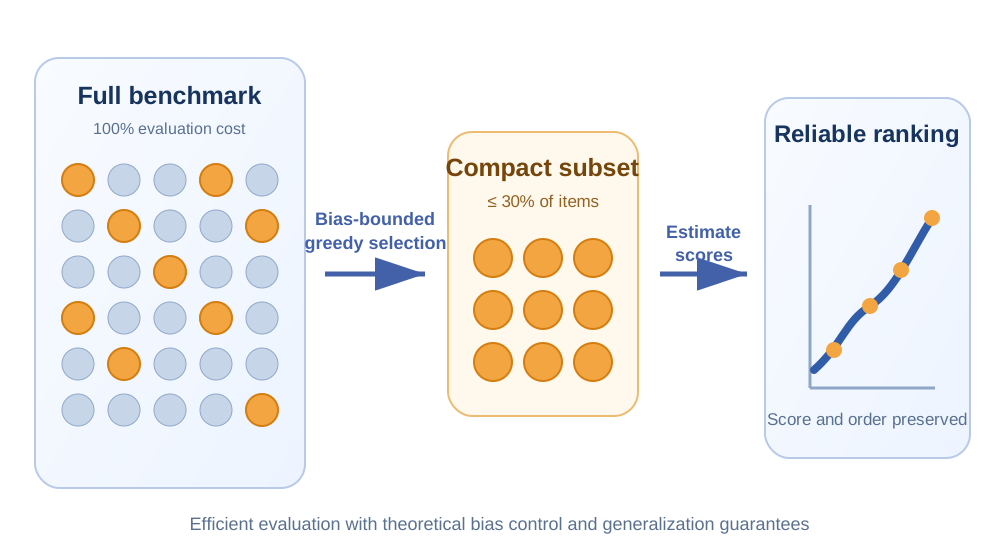
Efficient Benchmarking via Bias-Bounded Subset Selection
Yan Zhuang, Junhao Yu, Qi Liu, Yuxuan Sun, Jiatong Li, Zhenya Huang, Enhong Chen
IEEE Transactions on Pattern Analysis and Machine Intelligence, 47(12):11785–11801, 2025
- Formalizes efficient evaluation as a subset-selection problem, proves that the objective is submodular, and derives a simple greedy method with bias-control and generalization guarantees. Across 11 language-model benchmarks, the selected subsets preserve score estimates and model rankings while using no more than 30% of the original evaluation items.
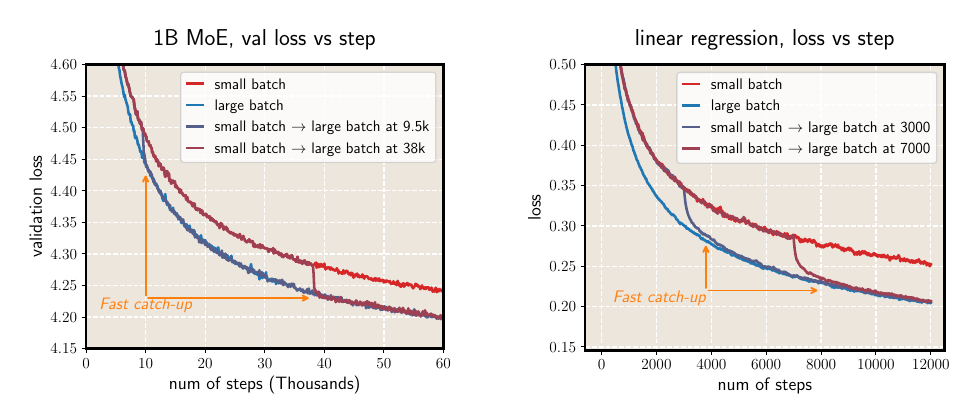
Fast Catch-Up, Late Switching: Optimal Batch Size Scheduling via Functional Scaling Laws
Jinbo Wang, Binghui Li, Zhanpeng Zhou, Mingze Wang, Yuxuan Sun, Jiaqi Zhang, Xunliang Cai, Lei Wu
International Conference on Learning Representations (ICLR), 2026
PDF · Code (Supplemental) · arXiv
- Extends functional scaling laws to batch-size scheduling and identifies a fast catch-up effect: on hard tasks, training can remain at a small batch for most of the run and switch late without losing the large-batch trajectory. Experiments across Dense and MoE language models from 50M to 1.1B parameters, with up to 1T training tokens, consistently favor late switching over constant or early-switch schedules.
TestAgent: An Adaptive and Intelligent Expert for Human Assessment
Junhao Yu, Yan Zhuang, Yuxuan Sun, Weibo Gao, Qi Liu, Mingyue Cheng, Zhenya Huang, Enhong Chen
Findings of the Association for Computational Linguistics: ACL 2025, 724–747
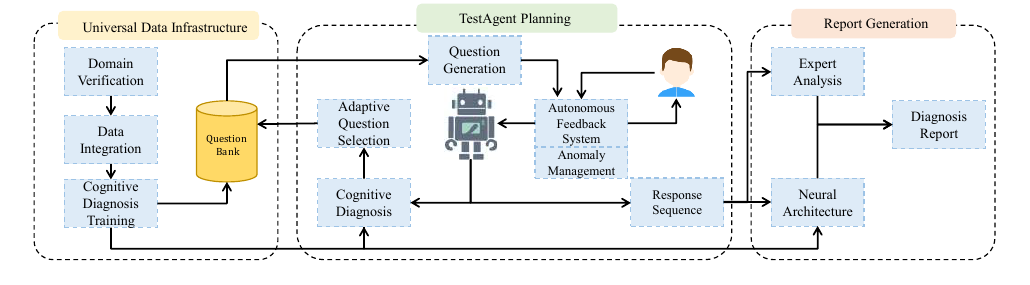
- Combines conversational LLM interaction with adaptive question selection, cognitive diagnosis, autonomous feedback, anomaly handling, and personalized report generation. Experiments spanning personality, educational, and mental-health assessment achieve comparable ability estimation with 20% fewer questions; a 50-person study also reports significant gains in fluency, speed, and interaction experience.
View all publications and current citation counts on Google Scholar.
🎖 Honors and Awards
- 2026 2nd Place, Global Open-source AI Challenge (GOAI), AI for Research — Algorithm Competition ( 2/2999 )
- 2026 First-Class Graduate Academic Scholarship, University of Science and Technology of China
- 2025 Outstanding Graduate, University of Science and Technology of China
- 2024 Soong Ching Ling Future Scholarship, University of Science and Technology of China
- 2023 Outstanding Student Scholarship Award, University of Science and Technology of China
- 2022 Outstanding Student Scholarship Award, University of Science and Technology of China
📖 Educations
- 2025.09 - present, Master’s Degree, University of Science and Technology of China, Computer Science and Technology.
- 2021.08 - 2025.06, Bachelor’s Degree, University of Science and Technology of China, Computer Science and Technology.
- 2018.09 - 2021.06, Senior High School Student, Zhengzhou Foreign Language School.
💻 Internships
- 2025.04 - 2026.07, Meituan, 3A Team, Post training.